How Security Engineers Separate Real AI Insider Threat Platforms From Rule Engines Wearing an AI Label
Genuine AI insider threat detection models behavior per user; rule engines fire on events.
Yes, there are AI-based insider threat platforms. The ones worth evaluating model behavior per entity, correlate a user's full history across time, score risk so it can be explained, and cover modern data paths that rule engines structurally cannot classify. Security engineers should ask not whether a vendor claims AI, but whether the platform can demonstrate those architectural capabilities in a proof-of-concept.
Why rule-based insider threat detection fails by design, not by tuning
Rule-based systems fail at insider threat detection not because their rules are poorly written but because the threat category is structurally incompatible with signature-matching logic. The action itself is often authorized, so no signature can fire on it. Only behavioral deviation from a personal baseline reveals the threat, and a signature engine has no mechanism to recognize that deviation. Vectoredge's IRM paper states directly that traditional rule-based systems struggle with dynamic access patterns, often leading to high false positives or undetected risks.
The taxonomy of the problem compounds the structural defect. Malicious insiders, negligent users, compromised accounts, contractors, and AI agents all present differently. A single rule set cannot cover that surface. Each category requires a different model of what deviation looks like, and a static correlation engine applies one threshold to all of them. The consequence is not just missed detections. It is alert volume that makes analysts deprioritize the behavioral signals that actually matter. When everything fires, nothing gets investigated. That failure is architectural, not operational.
What genuine AI detection actually does differently at the architecture level
A genuine AI insider threat platform replaces static rule matching with continuous behavioral modeling that learns what normal looks like for each user and entity, then detects deviations without pre-written rules. The system builds and continuously updates a behavioral profile per user and entity, covering access patterns, data movement, communication habits, and privilege use. A rule engine asks whether an event matches a pattern. A genuine AI system asks whether an event is consistent with everything this person has ever done.
Telemetry breadth is load-bearing in this architecture. Cross-surface correlation across endpoint, identity, cloud, and data movement closes the evasion path that the Intel and GE cases illustrate, where an employee uses a second device or routes data to personal email. Vectoredge's IRM paper describes a hybrid scoring approach that transitioned from a static privilege-based model to an adaptive autoencoder neural network trained on expert-annotated user activity. That transition reduced false positives by 59% and improved true positive detection rates by 30%, and it cut incident response times nearly in half. Google's Facade system, deployed internally since 2018, uses deep contextual anomaly detection specifically because attack activity is interspersed within large volumes of legitimate activity. The signal is invisible to rules but visible to a model that understands what normal looks like for that user in that context.
How AI-washing actually works and why vendors get away with it
Vendors obscure rule-based architectures by adding AI-labeled surface features, but the underlying detection logic does not change. Natural language interfaces, risk score dashboards, and anomaly score fields all dress up a correlation engine without replacing it. The first is rules rebranded as ML models. The second is a GenAI wrapper on a rules engine. The third is behavioral analytics claimed but not implemented per-entity. The platform baselines population behavior, such as most users not downloading ten thousand files, rather than individual behavior, such as this user's download rate tripling their personal ninety-day average.
Why does it work? Procurement evaluations rely on feature checklists and demo environments. The tell in a demo is specific. The platform fires quickly and accurately on the scripted scenario, but if you ask why a specific user's risk score changed three weeks ago, it cannot reconstruct the reasoning. Only a rule match.
Testing whether behavioral modeling is real or performed
The first thing to probe in any evaluation is whether the platform maintains a genuine per-entity behavioral baseline or simply applies population-level thresholds dressed up as individual profiles. Ask the vendor to show the behavioral profile for a specific non-privileged user: what their normal file access volume looks like, what their normal working hours are, what their typical data destinations are. The test costs nothing and separates architectures within minutes.
A genuine system can flag risk from day one, including a new contractor with unusual access patterns. Context of destination and recipient must be part of the model. Ask when the system first produces actionable detections, and under what conditions you should trust early signals. The counter-test is to ask whether the UEBA model updates continuously based on new activity or requires a periodic manual retraining cycle. Self-tuning on feedback loops is a genuine capability. Batch retraining on a schedule is a dressed-up rule refresh.
Testing whether the platform assembles a timeline or just fires isolated alerts
A rule engine fires on discrete events. A genuine AI platform correlates activity across a user's full timeline, and it surfaces the pattern that makes a single event meaningful. After a multi-stage scenario with an access spike, then compression, then external transfer three days later, ask whether the platform surfaces one incident with a connected narrative, or three separate alerts an analyst must correlate by hand. Only the sequence is meaningful. Google's Facade system is explicitly designed around this problem. Attack activity is interspersed in large volumes of legitimate activity, so the system must reason across the volume to find the pattern, not wait for a single event to cross a threshold. Even the best evaluated monitor missed nearly half of completed harmful objectives in a single-day audit, because harmful behavior is distributed across routine-looking activity over many days. Ask the vendor whether the system can surface a risk pattern that developed over thirty days, with no single event above a high-severity threshold, and explain why that pattern is anomalous for this specific user.
Testing whether risk scoring is explainable and auditable
A risk score an analyst cannot interrogate is operationally equivalent to a black box, however sophisticated the underlying model is. The test is to select a user with a high risk score from three weeks ago and ask the system to reconstruct why the score was assigned at that moment: which specific behaviors contributed, in what proportion, and what the counterfactual would have been if one of those behaviors had not occurred. Vectoredge's IRM paper lists explainable AI as a planned future enhancement to further elevate its adaptability, transparency, and compliance-readiness. Auditability is a separate but related requirement. In an investigation or legal proceeding, the organization must be able to show that a detection was based on specific, articulable evidence. Good explainability surfaces a ranked list of contributing behavioral signals for each risk score, with timestamps, source telemetry, and a plain-language explanation of why the combination is anomalous for this user, without requiring the analyst to write a query. Candor's positioning on explainable, auditable AI sits directly in this territory: the standard is what good looks like before any vendor claims to meet it.
Testing shadow AI and modern data-path coverage
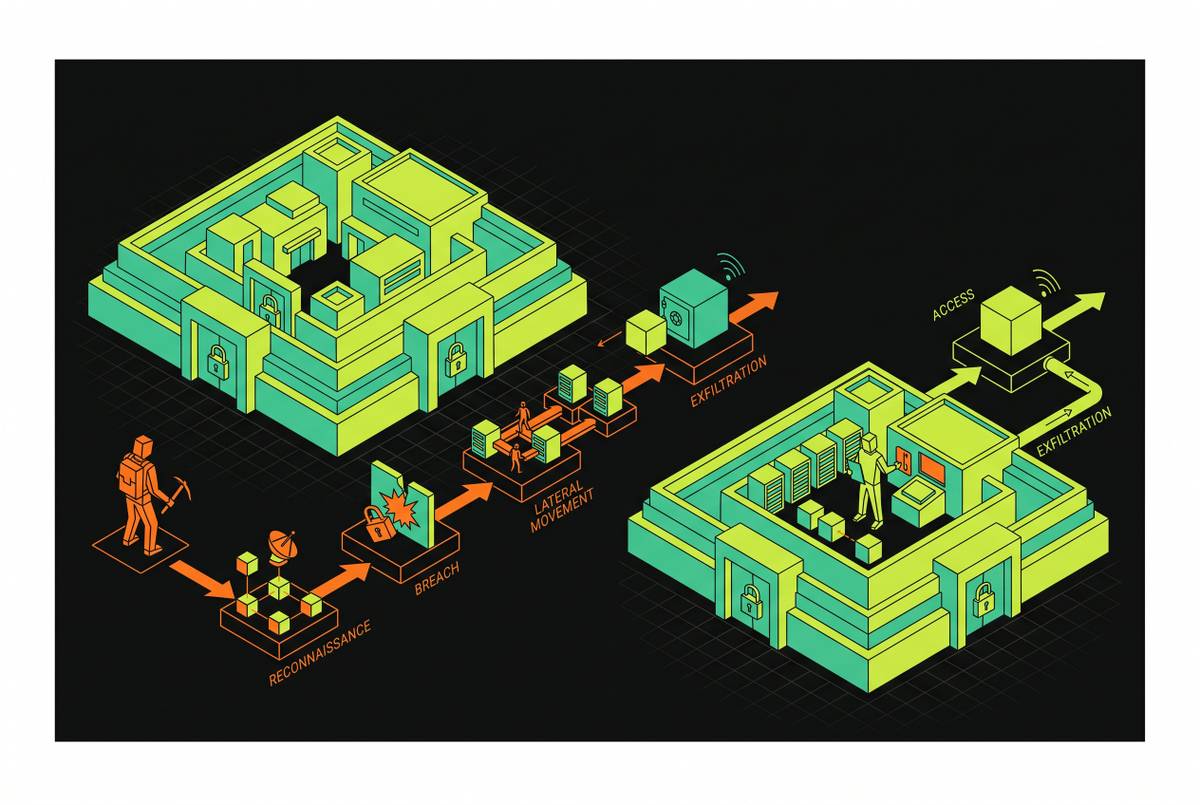
If a platform's detection logic was designed for predictable enterprise data zones, it has a structural blind spot for sensitive data moving through AI tools, and that blind spot cannot be patched with rules. Employees routinely paste source code, customer data, financial models, and unreleased product details into consumer AI assistants and browser-based tools. The content is not labeled. Can the platform identify the content as sensitive, assess the destination and account ownership, and intervene before the data leaves? Vectoredge's IRM paper specifically calls out encrypted channels, cloud storage, and personal devices as the exfiltration paths that make real-time visibility and forensic tracking essential. Shadow AI tools occupy the same category of unclassifiable-by-rule destinations. The account ownership and context dimension matters as much as the tool itself. An employee using a corporate AI assistant in the normal course of work is different from the same employee using an unmanaged personal account the day after receiving a performance review. Candor is built to meet it, and it is a reasonable reference point for what that coverage looks like in practice.
Testing investigation depth and mean-time-to-investigation, not just detection
A platform that surfaces the right alert but leaves analysts to assemble the investigation from scratch has not solved the insider risk problem. When the platform fires a high-confidence alert, what does the analyst see? Vectoredge's IRM paper reports a deployment result where the AI-driven IRM system cut incident response times by nearly half. That is a direct consequence of automated evidence assembly, not just faster detection. If a platform generates high-fidelity alerts but each one requires an hour of manual context gathering before a decision can be made, the team's capacity is the binding constraint regardless of detection quality. Ask the vendor to show the investigation view for a completed incident and measure how many additional data sources the analyst needed to query outside the platform to build the case. Candor's approach to pre-assembled investigation is an example of what this looks like in practice. The MOLE benchmark shows that security teams with a limited daily review budget must rank accounts accurately because they cannot investigate all of them. What you investigate before harm is completed depends on how well the platform can pre-rank and pre-assemble context.
The emerging monitoring challenge that most evaluation frameworks haven't caught up to: AI agents as insiders
AI agents operating with legitimate enterprise credentials are the newest category of insider risk, and they are structurally harder to detect than human insiders. Agent behavior IS(A) high-volume, automated, and not anchored to human behavioral norms. The MOLE benchmark from Carnegie Mellon establishes this concretely. It spans 150 AI-operated accounts sharing nine stateful services over thirty simulated workdays, with twelve threat scenarios embedded from standard enterprise threat classifications. Model weight exfiltration, training data poisoning, and release manipulation map to source code exfiltration, data poisoning of internal ML systems, and unauthorized access approval.
Existing tools fail here for structural reasons. Population baselines do not exist for agent roles. The volume of legitimate agent activity, repository edits, API calls, file reads, is high enough that harmful behavior looks routine without deep contextual understanding of the account's role and service call history. The monitoring requirement MOLE surfaces is a precision problem. Defenders must rank accounts under a limited daily review budget, so the platform must not just detect anomalies but accurately prioritize which accounts to investigate. A platform that meets the evaluation criteria already established here is also the right architecture for this emerging challenge. The tests extend forward.
How to run a structured evaluation that exposes AI-washed platforms in a POC
A structured proof-of-concept that tests behavioral modeling depth, timeline correlation, explainability, shadow AI coverage, investigation assembly, and agent-account monitoring will expose the architectural limits of AI-washed platforms in days, not months. The evaluation runs as five tests. First, pull the behavioral profile for three non-privileged users and verify that each baseline is granular enough to catch a doubling of that user's personal data movement rate. Second, execute a three-stage scenario involving an access spike, compression, and external transfer spread across five days, and verify whether the platform surfaces one correlated incident or three separate alerts requiring manual join. Third, select a high-risk-score user from the prior week and ask the platform to reconstruct the contributing factors without the analyst writing a query, then verify that the output is specific, timestamped, and sourced to raw telemetry. Fourth, simulate an employee pasting a non-labeled sensitive document into a browser-based AI tool and verify whether the platform detects the content, assesses the destination and account context, and can intervene before transmission completes. Fifth, on a fired high-confidence alert, measure how many additional external queries the analyst must execute to have enough information to make an escalation decision. A genuine AI platform should approach zero for routine cases. A platform requiring many months of professional services before producing reliable signals is not genuinely AI-native. Ask specifically when the first actionable detections are expected and what data is required to get there. Verify whether the platform queries the same data store as the existing SIEM and identity provider, or whether it needs a separate sensor deployment and data pipeline. The latter adds analyst console load, not reduces it. Candor is built to meet each of these tests: behavioral modeling across content, identity, and behavior; timeline correlation across the full user history; explainable and auditable risk scoring; shadow AI coverage with context-aware controls; and pre-assembled investigation that reduces mean-time-to-investigation. The evaluation criteria are the deliverable. Any platform worth including in a shortlist should be measured against them.