The Security Team's Exit Ramp From a UEBA Deployment Drowning in False Positives
Statistical anomaly detection can't distinguish breaches from normal behavior changes.
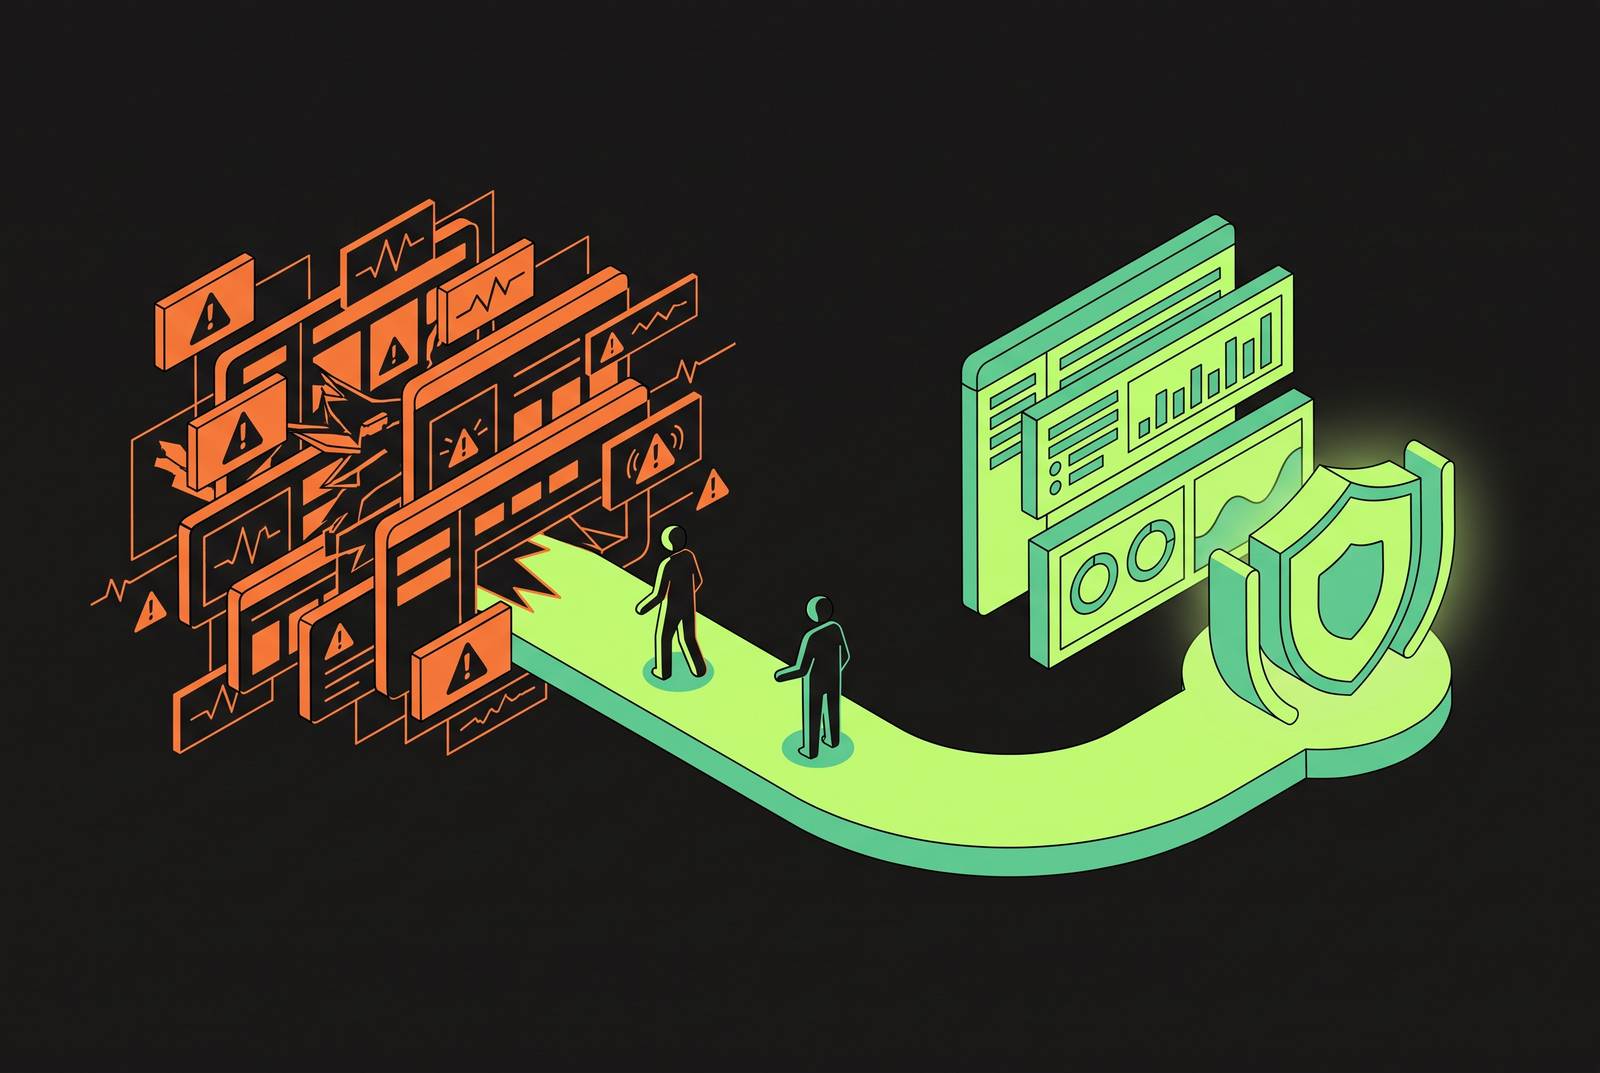
A UEBA deployment that keeps burying analysts in false positives is not misconfigured, it is working as designed. Statistical anomaly detection treats distance from a behavioral baseline as a proxy for threat, and that proxy fails in both directions: it fires on normal behavior that looks unusual and stays silent on genuine risk that looks routine. The way out is detection built around what the data is, where it is going, and who is touching it, running alongside the behavioral context of that person, instead of how far today's activity sits from yesterday's average.
Why UEBA deployments generate more noise than signal
User and entity behavior analytics platforms work by building a personalized baseline for every user and system account: typical login hours, typical access locations, typical data volumes moved in a session. The premise is that abnormal behavior and dangerous behavior are close enough to the same thing that scoring one will catch the other.
That premise breaks down the moment a person's job changes. The system has no way to tell a promotion from a compromise, because both look, mathematically, like the same thing: a point that falls outside the historical pattern.
The more serious failure runs in the other direction. If an employee exfiltrates data slowly, staying inside the access patterns they use every day, the deviations are too small to ever trip a threshold. A compromised account using its legitimate owner's valid session behaves exactly like that owner and generates no anomaly. But an adaptive baseline is still a baseline. It still assumes that risk concentrates at the statistical edge of behavior, and that assumption is what produces a system biased toward volume: unable to tell the two failure modes apart at the point of detection, it has to fire broadly just to avoid missing the cases that matter.
The alert pile growing faster than teams can retire it
Alert volume in a mature UEBA deployment does not level off.
Rule accumulation is the most visible driver. A rule stays in place even after the threat it addressed stops being relevant, so the detection surface only ever grows.
Recent preprint research (arXiv:2608.31062) calls this the exclusion ratchet. When a UEBA system generates too many alerts, the instinct is to write a suppression rule that silences the noisy alert type. A team can spend years suppressing its way to a quieter dashboard while the actual detection surface shrinks beneath it, because nothing in the system flags the absence of a signal that used to exist.
What alert fatigue costs a security team
The costliest part of a UEBA deployment drowning in false positives is the gap between alerts generated and alerts actually investigated, because that gap is where breaches complete undetected. Most daily security alerts go unaddressed because alert volume exceeds the cognitive and staffing capacity available to review it, not because analysts are careless.
Teams try to push back against this, but habituation is why the gap persists anyway. Research on risk-based alerting frames this as a signal-quality problem rather than a volume problem: cutting the number of alerts does not restore analyst trust on its own, because the alerts that remain still have to prove they are worth acting on, every time, before confidence returns.
Insider risk sits at the worst possible point in this chain. And the damage does not stop at the individual alert: teams that cannot trust their own tooling lose their most experienced analysts to burnout and turnover, and the institutional knowledge required to tune the system correctly leaves the building with them.
The three insider risk patterns that statistical UEBA is worst at catching
The insider risk events that do the most damage share a structural trait: the behavior looks ordinary until the moment it does not, and by the time a statistical anomaly fires, if it fires at all, the damage is largely done.
Pre-departure intellectual property exfiltration is the first pattern. In both cases, the real failure occurred before any UEBA alert had a chance to fire: offboarding and access governance broke down first, and no amount of anomaly-score tuning closes a gap that originates there.
Compromised identity is the second pattern, and it is the one statistical detection is least equipped to touch, because there is nothing statistically unusual to find. The attacker has inherited the account's behavioral baseline along with its password, so no anomaly fires, because no anomaly exists.
What links these archetypes, along with a slower-moving third category of negligent or accidental exposure, such as an employee pasting sensitive records into an unsanctioned tool without any malicious intent, is where the actual risk lives. It lives in what the data means, where it is headed, and the behavioral context surrounding the person who touched it. None of that is visible to a system that only measures distance from a statistical average.
Why tuning the existing system cannot close the gap
Every tuning adjustment made to a statistical UEBA system works by moving a threshold, and when you move a threshold in one direction, a gap opens somewhere else. If you raise the bar to quiet a noisy rule, genuine detections in that same category now have to clear that higher bar too. The system gets quieter and less sensitive in the same motion, and that trade is not a solution, it is a different set of blind spots wearing the old dashboard.
Tightening policy at the endpoint does not make the underlying behavior stop, it relocates it. Static, channel-oriented DLP cannot follow risk as it moves this way. Alert fatigue research reinforces why the human side of this cannot absorb the difference either: the gap between incoming alert volume and available analyst capacity is a matter of arithmetic, and adding another round of tuning without changing the underlying ratio of signal to noise only delays the return of the same backlog. The sensitivity dial was never what needed adjusting. It has been measuring the wrong thing from the start.
Detection that understands both the data and the person
Insider risk detection that actually works has to answer four questions at once: what the data is, where it is going, who is touching it, and what the surrounding behavior pattern says about that person right now. A statistical anomaly score cannot reliably answer any of the four.
Understanding the data starts with recognizing that the most sensitive information an organization holds frequently carries no classification label. Intellectual property becomes sensitive because of what it means to the business, not because it matches a regex pattern, so detection that cannot read the content itself cannot judge the risk attached to it. An unlabeled file moving to a personal cloud account in the middle of an active investigation carries a very different level of risk than the same unlabeled file moving to a sanctioned collaboration tool, even though the label, or lack of one, looks identical in both cases.
If you understand the destination, you recognize that risk depends heavily on where data is headed. A personal email account, a public paste site, an unsanctioned generative AI interface, and a competitor's domain each represent a distinct threat profile, and a volume-based anomaly score cannot tell them apart. Generative AI inputs deserve particular attention here: sensitive data typed into an external AI model leaves the organization's control envelope immediately and without any visible trace, and static DLP has no mechanism for evaluating either the content submitted or the account on the receiving end.
If you understand the person and the pattern, you treat a single event as almost never the real signal. The risk sits in the pattern across a user's full timeline. A risk score that updates continuously as behavioral context accumulates, rather than one that fires only when a single threshold gets crossed, moves closer to the right architecture, but only if the scoring stays grounded in data and destination context, instead of defaulting back to statistical deviation. None of this works without explainability: a detection that cannot show an analyst what data, what destination, what behavioral context, and what prior events drove the alert leaves that analyst reconstructing the reasoning from scratch, which is the same burden a false positive creates.
How behavioral DLP and insider risk platforms approach this differently
A handful of platforms reduce false positives by changing what triggers an alert in the first place, rather than suppressing alerts after a statistical model has already fired.
Candor is built on exactly this premise: an AI-native DLP and insider risk platform designed to protect sensitive data and detect insider risk by understanding the data and the person behind each event together. Deployment is designed to run within a single week, with the exact timeline depending on whether the environment is on-premise or cloud-based, which matters because every additional week spent running a legacy UEBA deployment is another week of suppression rules and coverage gaps accumulating underneath it.
AI-powered UEBA, as a category distinct from any single vendor, has made real improvements over static, rule-based SIEM detection. This approach cannot reliably surface risk that stays statistically normal, intellectual property with no classification label, or a compromised account that inherits its legitimate owner's behavioral profile. It functions best as one layer in a broader detection stack.
Risk-based alerting approaches move the conversation forward by scoring alerts according to the likely risk or impact of the activity detected, factoring in asset sensitivity, user privilege level, and threat model alongside deviation magnitude. That is a genuine improvement in signal quality over raw anomaly volume, and it reduces analyst burden without relying on suppression rules. What it does not resolve is the underlying data-understanding gap: a risk-scored alert about an unclassified file moving to a personal account gets prioritized correctly relative to an unscored one, but neither alert tells the analyst what the file actually contains or why that particular destination is dangerous.
Applied to a low-fidelity alert stream, it speeds up disposition but cannot manufacture context that was never captured.
The investigation workflow changes that reduce mean time to conclusion
Getting the detection right only solves half of the problem. A platform that surfaces the correct alert but still leaves the analyst to reconstruct the case from raw, disconnected logs has not actually closed the time gap between first signal and a defensible conclusion.
Most SOC capacity disappears in the stretch between acknowledging an alert and reaching a conclusion with a concrete plan attached. If an alert takes an analyst forty minutes to piece together from scattered sources, it behaves, operationally, exactly like a false positive, because the backlog means it frequently never gets that forty minutes in the first place. What arrives in the queue is a structured summary with a disposition recommendation, not a raw event requiring reconstruction.
The clock that matters here belongs to the attacker, not the analyst. Mean time to conclusion, MTTC, is the metric that captures what actually matters in this window: the span from first signal to a defensible answer with a plan attached, with detection time, acknowledgment time, and investigation time collapsed into a single number rather than tracked separately, because tracking them separately hides the real operational gap between them.
Pre-assembled evidence is the structural change that moves MTTC. When a platform delivers an alert already attached to the full behavioral timeline, the data involved, the destination, and the relevant prior events, the analyst's job becomes judgment. Candor's approach follows this logic directly: tools that combine behavioral profiling with data-aware investigation can triage candidate insider risk events and present only the ones backed by demonstrable evidence, which lets a team restore confidence in its alerting without stepping back onto the tuning treadmill. None of this works without an audit trail attached to the reasoning. A disposition recommendation with no visible logic behind it recreates a black box under a new name, since analysts cannot evaluate or override a judgment they cannot see.
The program structure that stops the false-positive problem from rebuilding itself
A stronger detection architecture buys a security team time. It does not, on its own, stop suppression rules from accumulating again, because without a program structure governing how rules get created, owned, and retired, the exclusion ratchet simply starts over.
The fix starts with use case discipline. Insider threat programs hold up best when anchored to a small number of use cases tied to material business risk, departing employees, contractor offboarding, privileged access abuse, large-scale data exports, sensitive-record access, SaaS oversharing, and shadow AI inputs, rather than attempting to monitor everything at once and tune toward coverage after the fact. Each of those use cases needs a named owner, a defined escalation path, and a set review cadence, because suppression rules accumulate precisely in the absence of anyone with the authority or accountability to retire them.
Cross-functional ownership has to be settled before an investigation starts, not during one. Security cannot carry insider risk investigations alone: HR manages the personnel and legal dimensions, security validates alerts and supplies the technical evidence, and legal defines what evidence collection is permissible in the relevant jurisdiction. All three need a seat at the table from the first alert, because improvising those boundaries mid-investigation creates legal exposure and slows down the response exactly when speed matters most.
A team that adds suppression rules and raises thresholds is not making progress, no matter how quiet the dashboard looks.